 Lê Chí Đại
ML Benchmark Suite
A team project for comparing learning pipelines across different kinds of data, with published reports that explain preprocessing, feature representations, and model behavior.
Project visuals
Figures from project reports, pitch decks, and saved experiment outputs. Select an image to open it at full resolution.
The project
The suite brings tabular, text, image, and speech experiments into a shared project website. Each report explains its data preparation and model comparisons, with links to code, datasets, and notebooks.
Configurable tabular pipelines
The Spaceship Titanic work compares imputation, scaling, encoding, dimensionality reduction, and missing-value handling across classical, boosted, and deep tabular models. A configuration module supports running and logging combinations without manually rewriting each pipeline.
Text and image representations
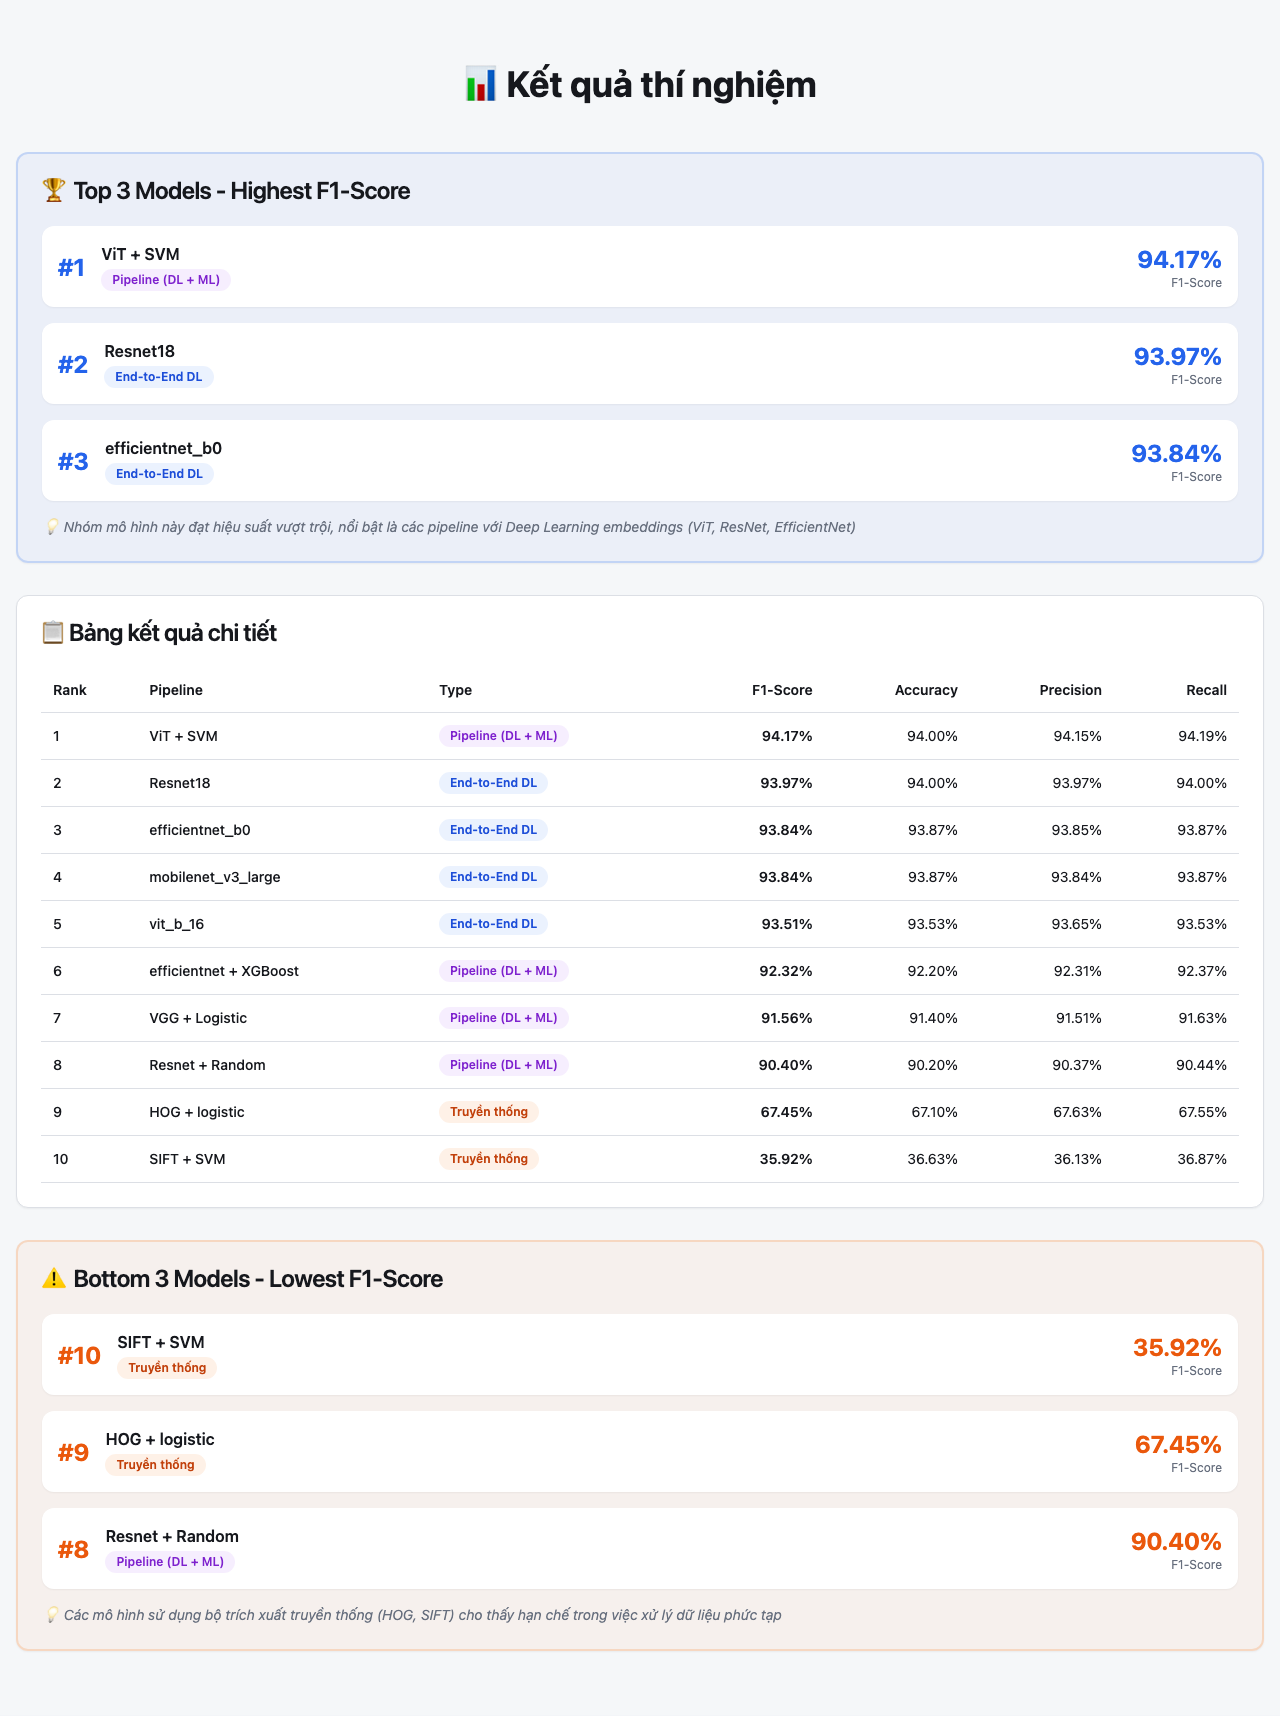
The review-rating report compares bag-of-words and TF-IDF pipelines with sequence models and DistilBERT. The Intel scene-classification report compares HOG/SIFT features, deep embeddings paired with classical classifiers, and end-to-end neural networks.
Speech extension
The spoken-digit extension adds an MFCC feature pipeline, Hidden Markov Models, and a Gradio demo. It remains documented separately in the Spoken Digit Recognition case study as one component of the broader suite.
Team work and evaluation
Built for CO3117 by Lê Chí Đại, Nguyễn Quốc Huy, Phạm Lê Tiến Đạt, and Võ Văn Thịnh. The reports preserve the evaluated datasets and model configurations so each comparison can be read in context.