 Lê Chí Đại
VisionDrive3D
A hierarchical rendering engine for generating synthetic datasets that mimic multi-camera autonomous driving configurations.
Project visuals
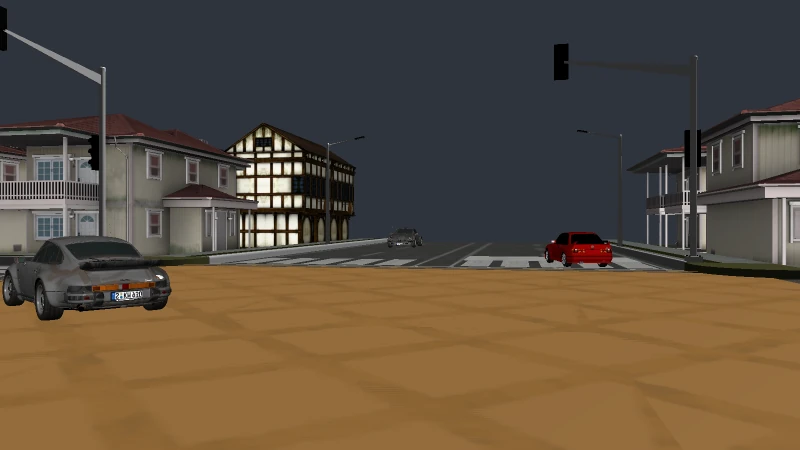
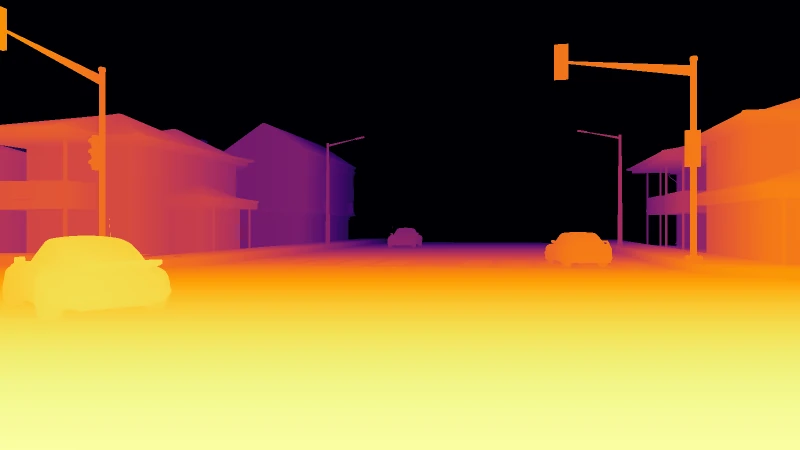
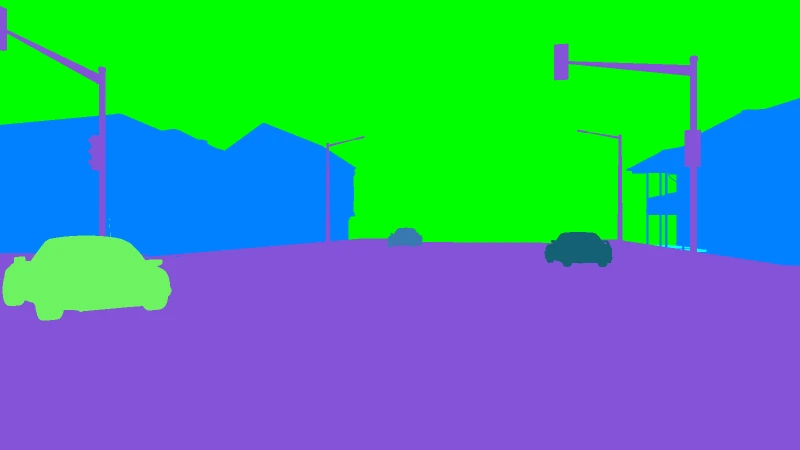
Figures from project reports, pitch decks, and saved experiment outputs. Select an image to open it at full resolution.
The problem
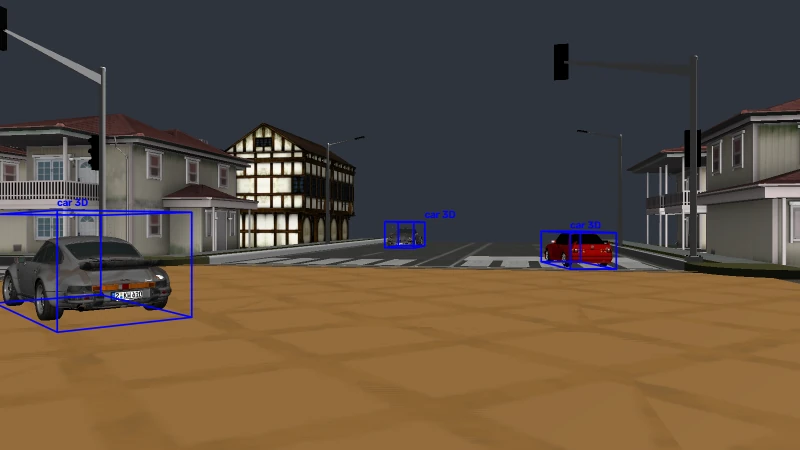
Training perception models requires images and reliable annotations. Synthetic scenes make it possible to control camera configurations and produce multiple ground-truth representations from the same scene.
My contribution
Co-engineered the rendering pipeline and built hooks to capture raw frame buffers. Automated annotation export into COCO JSON and YOLO text formats, and authored GLSL fragment shaders for synchronous RGB, depth, and instance segmentation outputs.
Evaluation
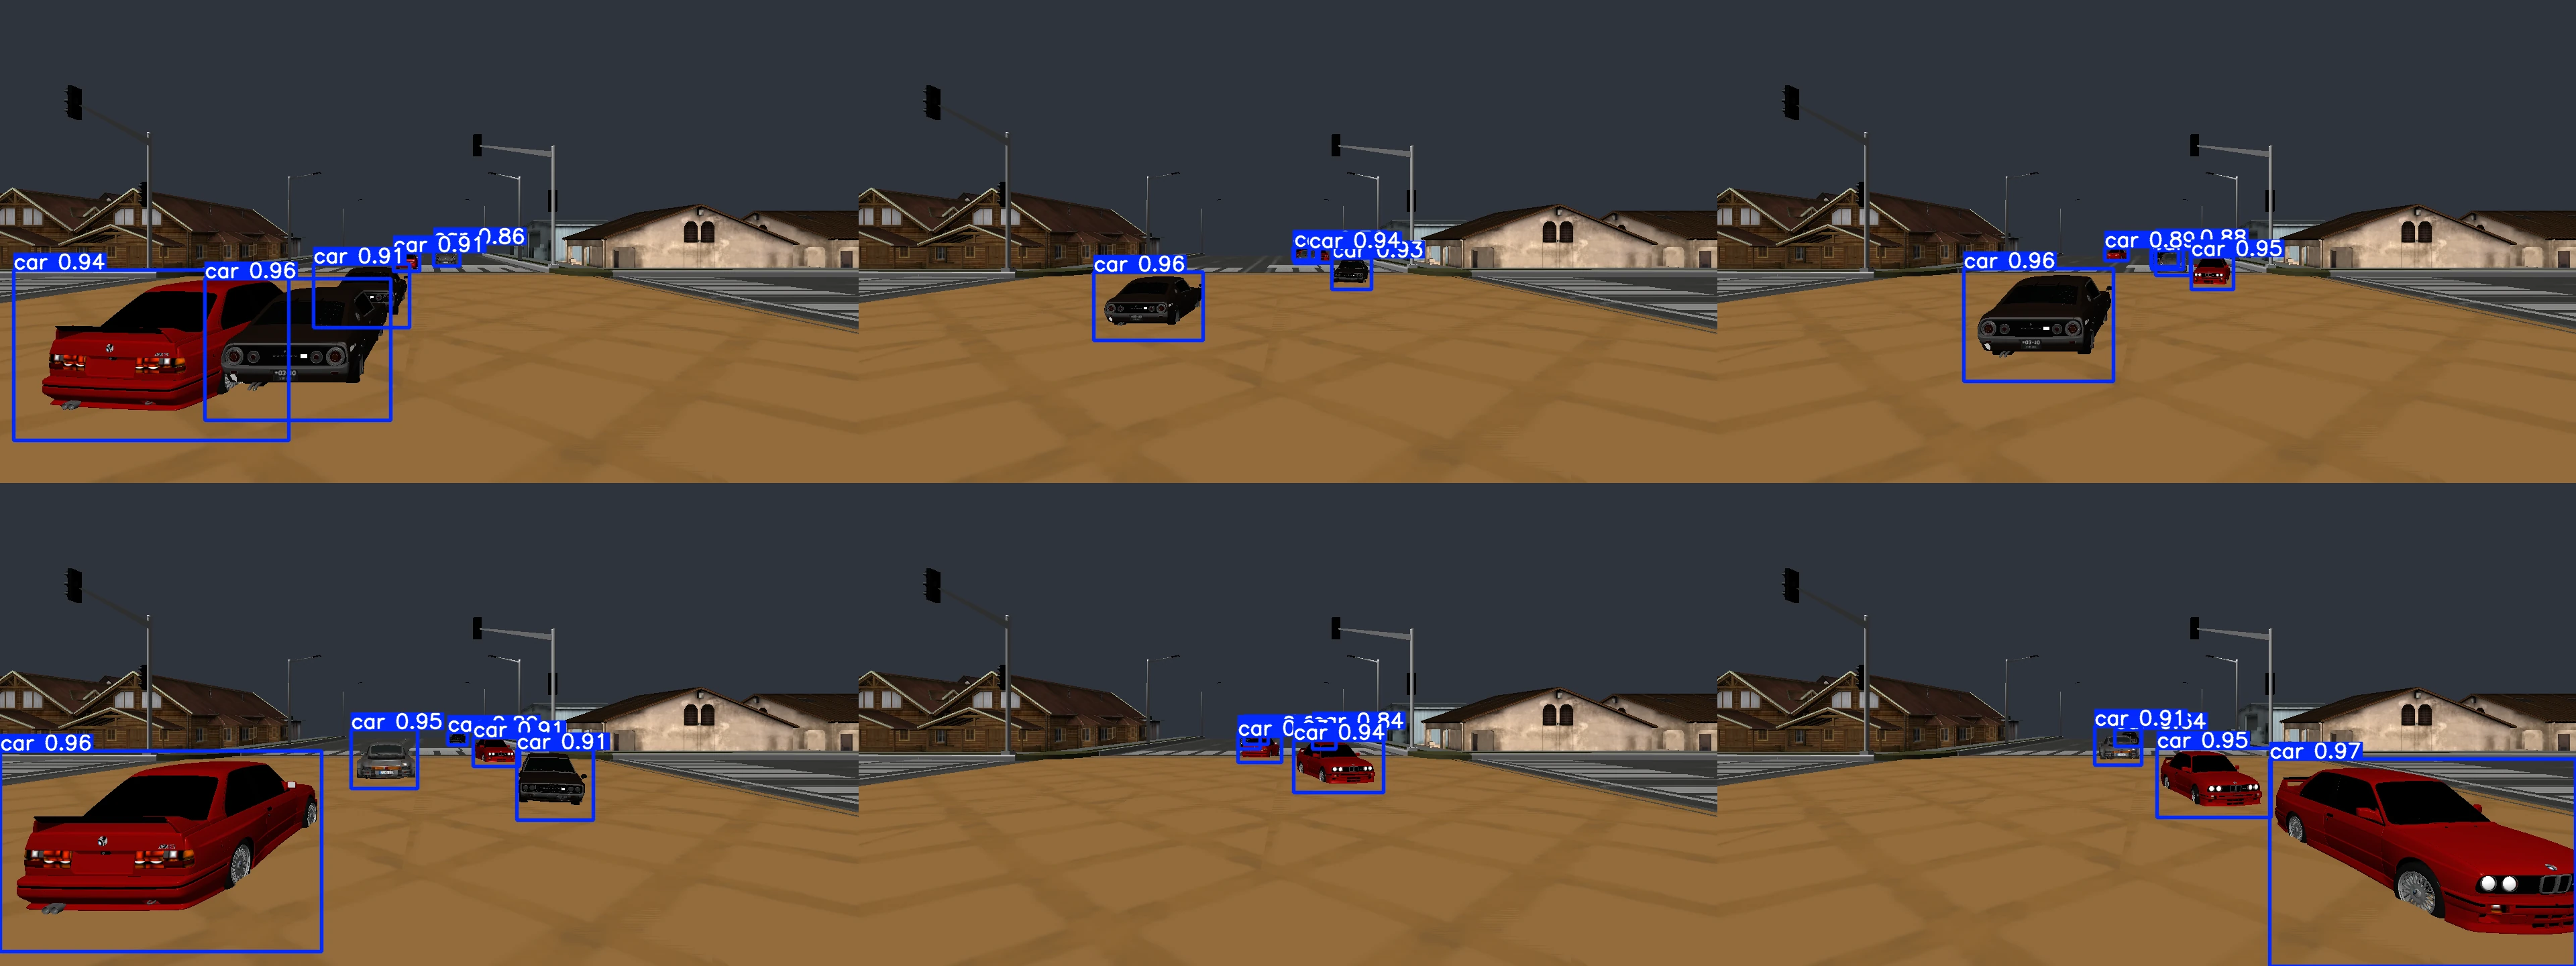
Benchmarked YOLOv8s, RT-DETR-L, and Faster R-CNN to examine cross-dataset generalization and the trade-off between detection accuracy and inference latency. Observed results span 0.694–0.934 mAP@50 and 8.2–22.0 ms across evaluated configurations; these are not a single-model before/after improvement.
The important limitation
Synthetic data is not a substitute for real-world evaluation. Rendering assumptions, scene diversity, and camera geometry all affect transfer. Results need to be interpreted within the evaluated dataset and hardware setup.